Quantinuum reports five logical memory errors per million rounds
Helios improves a logical-memory benchmark and separately tests protected Clifford operations. The statistics and workload define what each rate means.
The result
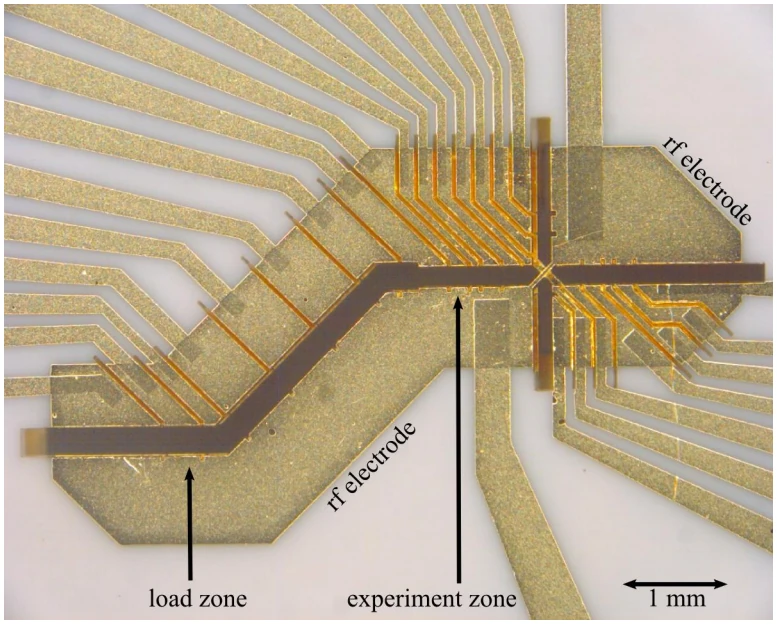
Quantinuum’s newest result comes with a number worth reading carefully: the company reports a logical-memory failure probability of five in a million syndrome-extraction rounds on Helios. Its October 19 announcement describes color-code experiments with increasing protection. The technical report says the largest tested distance reached 99.9995% fidelity per round.[1][2]
A round is a unit, not a whole algorithm
The distinction is what makes this a useful story. A memory experiment asks whether encoded information survives repeated checks. A useful calculation also has to create its inputs, perform the required logical operations, coordinate classical decisions and produce a trustworthy output. Progress on one of those jobs can be substantial without completing the others. Think of a computer that has acquired a much more dependable memory component: that expands what its designers can attempt, but does not tell you the performance of every program.
What the scaling evidence adds
A single impressive error rate describes one operating point. Evidence that adding protection reduces failures addresses a more consequential engineering question: can making the system larger make it more reliable? The company reports that direction of improvement across its tested code distances. QubitWire’s interpretation is that the slope deserves at least as much attention as the best endpoint. The next useful comparisons should keep the experiment’s duration, decoder behavior, accepted data and operation type attached. A percentage loses meaning when those conditions disappear.[2]
The statistical and operational context
The technical manuscript provides the statistical context: its distance-seven memory experiment used 29,000 shots with 20 checking rounds per shot. Three failed shots under the main decoder produced an estimated per-round error rate of 5 × 10⁻⁶, with a reported 68% interval from 3 to 9 × 10⁻⁶. All decoding in this study was performed offline; streaming-decoder timing was investigated separately.[3]
The same manuscript separately reports below-threshold logical two- Clifford randomized benchmarking at code distances three and five. At distance five it estimates an error of roughly seven in 100,000 per logical Clifford. That is evidence for protected operations as well as memory. It remains a different benchmark from the memory-round figure, and neither alone measures a complete universal application.[3]
Closing the feedback loop
The Frontier streaming-decoder timing test used previously acquired syndrome data on a local laptop. It measured decoder execution rather than the complete feedback loop, which adds runtime and communication overhead. The paper identifies two further integration targets: below-threshold scaling of magic-state preparation, and a full Clifford-plus-T circuit with real-time decoding. These would connect the protected memory and gate components into a broader computational test.[3]
What to watch next
The next integration test is a complete application or universal logical workload with its runtime and online feedback included. Readers can compare the required operations, success criterion, accepted output and elapsed time. Those quantities would show how the reported memory and Clifford benchmarks work together in a useful task. They would also allow software and code choices to be assessed without treating the corporate roadmap as an experimental observation.
For now, the useful takeaway is precise: stronger evidence for a dependable logical memory, with the full computational workload still a separate question.
A result should carry its denominator
Every rate needs a denominator: per correction cycle, per logical gate or per completed circuit. These units determine which calculation is legitimate. They also identify missing information. A memory rate alone does not tell a user how many correction rounds a particular gate requires or whether an algorithm needs an operation characterized under different conditions.
Confidence intervals matter as well. Rare failures can be difficult to estimate precisely, especially if the measurement contains few observed events. The central estimate, the amount of evidence and the statistical method should travel together. A change in the reported rate may otherwise appear more decisive than the available data warrant. The remaining uncertainty concerns the complete logical workload, including gates, waiting periods and the final readout.
Longer sequences and a broader set of operations can therefore reveal limitations that repeating the highest-fidelity memory measurement would miss.
Research in context · checked 20 Oct 2026
Why tiny error rates can still matter in long calculations
A worked explanation of the distinction behind the result.
Consider a deliberately simplified machine with a failure probability of one in 100,000 on each operation. This is a hypothetical example, not a prediction for Helios. Assume the failures are independent, that every failure ruins the answer and that the probability stays constant. If the machine performs m operations, the probability that none fails is (1 - 0.00001)^m. The assumptions do almost as much work as the arithmetic.
After 1,000 operations, that probability is about 99%. After 100,000 it is about 36.8%. The calculation does not say that quantum machines inevitably fail at those depths. It says that a component rate and a whole-program rate are different quantities. The desired program success rate determines how small the relevant component errors must become, how the program is organized and how much correction is required.
There is a second lesson. Two systems can report the same average error rate while behaving differently over a long sequence. One might suffer rare bursts that affect many consecutive operations. Another might fail independently. The average alone cannot tell you which description applies. Repeating a short test many times is therefore not automatically equivalent to running one long computation.
Changing the hypothetical error probability or operation count changes the independent-error prediction. A burst model can have the same average error rate and a different distribution of outcomes. Correlations and time dependence therefore belong beside the average rate when judging a hardware result; another decimal place cannot supply that missing structure.
Sources and evidence
- Quantinuum error-correction announcement ↗Source published 2026-10-19. company announcement.
- Quantinuum Closes In on One Million Error-Free Operations ↗Source published 2026-10-19. company technical report. Fidelity is per syndrome-extraction cycle.
- Quantum error correction well below the color code threshold ↗Technical manuscript; reported memory statistics and separate Clifford benchmarking; decoding was offline.
Research in context · checked 20 Oct 2026
Does correcting a qubit mean looking directly at its information?
A worked explanation of the distinction behind the result.
Error correction is designed around a careful distinction: learn something about an error without learning the protected answer itself. A rough classical analogy is a consistency check that tells you two entries disagree without revealing the confidential entries. The quantum implementation is more constrained because an arbitrary unknown state cannot simply be copied into backup files.
The useful mental picture is a pattern of checks distributed across an encoding. A decoder interprets that pattern. The protected information is represented jointly, so the story is about how the checks behave together, not about one physical object becoming perfectly stable. This also explains why a logical-memory result should report the checking cycle and decoding assumptions. They are part of the device being assessed, not administrative details around it.
The independent-error example is deliberately restrictive. Correlations, changes in calibration and different operation types can invalidate its assumptions. Its value is to expose the unit conversion a headline requires, then make clear which additional evidence is needed before the same arithmetic can describe an actual algorithm.
Sources and evidence
- Quantinuum error-correction announcement ↗Source published 2026-10-19. company announcement.
- Quantinuum Closes In on One Million Error-Free Operations ↗Source published 2026-10-19. company technical report. Fidelity is per syndrome-extraction cycle.
- Quantum error correction well below the color code threshold ↗Technical manuscript; reported memory statistics and separate Clifford benchmarking; decoding was offline.
Keep your reading trail
Keep up with these topics
Choose the subjects you want to find again in Your Updates.